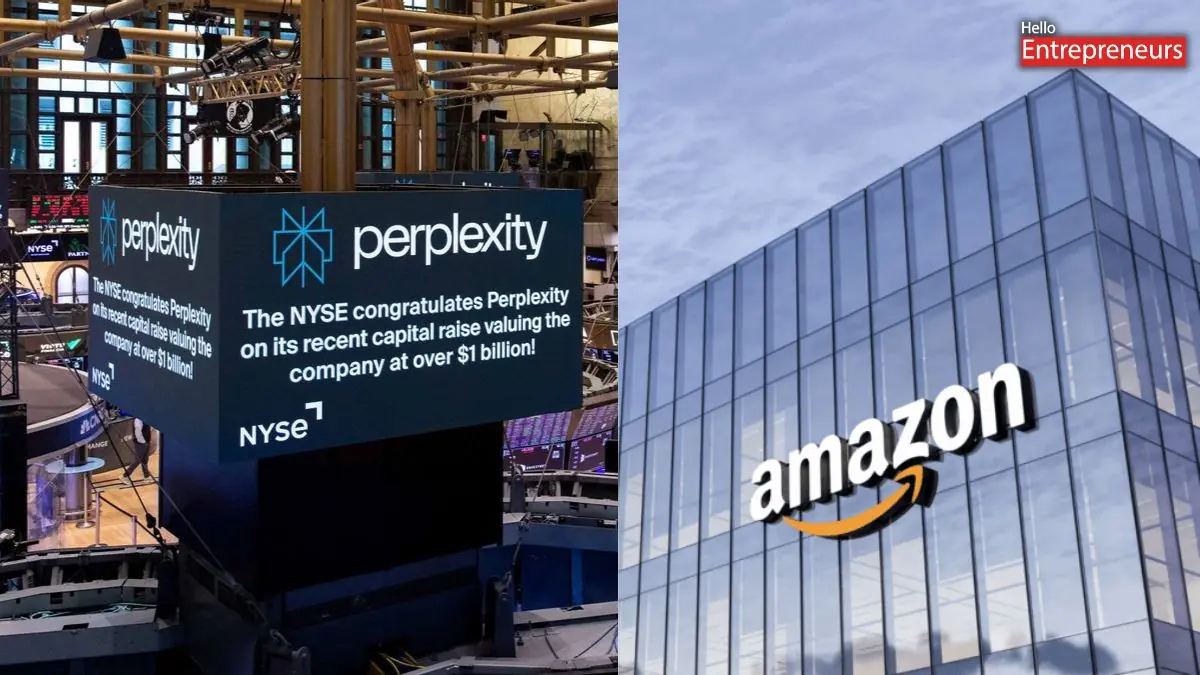





New Delhi: Amazon recently hit back at Perplexity AI after serious accusations that the smaller AI company was scraping data from Amazon’s platforms without permission. The controversy has triggered a big debate on data rights and fairness, and how AI firms should get their training materials.
Perplexity AI designs AI-powered question-answering and summarization tools. According to Amazon, this company used content from Amazon’s websites in ways violating its policies. Its lawyers reportedly warned Perplexity that the practice may raise a legal issue. They said using this data without a license is unfair and will hurt Amazon’s businesses.
But Perplexity isn’t backing down. They say that scraping publicly available data is at least covered under some laws and that they aren’t infringing any copyright. To them, they must have the capability to use public data in order to build strong, useful AI systems. And they claim that Amazon’s public push might have more to do with protecting its interests than high moral ground.
The conflict is closely watched by some technology and legal experts, who consider the case setting an important precedent for the way other AI companies may approach the collection of data. If Amazon wins, that could discourage smaller firms from using publicly available content to improve their models. If Perplexity wins, it could mean more freedom for AI startups to build by using publicly accessible data.





