




New Delhi: Google has officially unveiled its Gemini Robotics ER 2, an embodied reasoning model for robotics that combines video understanding, task orchestration, and multi-robot collaboration. This model allows robots to understand the physical world, interact with humans, plan multi-step tasks, and adapt their actions based on real-time situations. Gemini Robotics ER 2 works as a high-level reasoning layer for robots, while lower-level Vision-Language-Action models handle the motor and developer-defined functions, enabling robots to gather information and complete tasks by using connected capabilities.
Compared with the Gemini Robotics ER 1.6, this model adds improved video understanding, progress tracking, and multi-robot collaboration. By analyzing continuous video feeds, robots can monitor their progress, recover from errors, and determine when to move to the next step. This model can also reason about the upcoming actions while the robot is performing the current task. Gemini Robotics ER 2 acts as a physical agent that can orchestrate multiple steps, self-correct during tasks, and adapt to unfamiliar situations. Developers can connect low-level control interfaces by including Vision Language Action models and navigation APIs as tools and stream multimodal video, audio, and text inputs directly into the model.
Google evaluated Gemini Robotics ER 2 by using simulated robots, real-world robot control, and human tele-operation setups. The model improves tool orchestration performance compared with Gemini Robotics ER 1.6 across real VLA, simulated VLA, and human tele-operation control modes. Gemini Robotics ER 2 integrates with the Gemini Live API via a bidirectional streaming endpoint, which is specially designed for latency-sensitive robotics tasks. This enables the model to coordinate action models and robotics APIs while reducing delays between reasoning and execution.
Google also demonstrated the model with Boston Dynamics’ Spot robot, where Gemini Robotics ER 2 controls Spot APIs, including navigation and manipulator movement, to fetch objects by using natural language commands. It improves video understanding and progress tracking by enabling robots to verify whether complex tasks, such as tightening a light bulb or tying a trash bag, are completed before moving to the next step. This upgrade focuses on two areas: progress classification and moment finding.
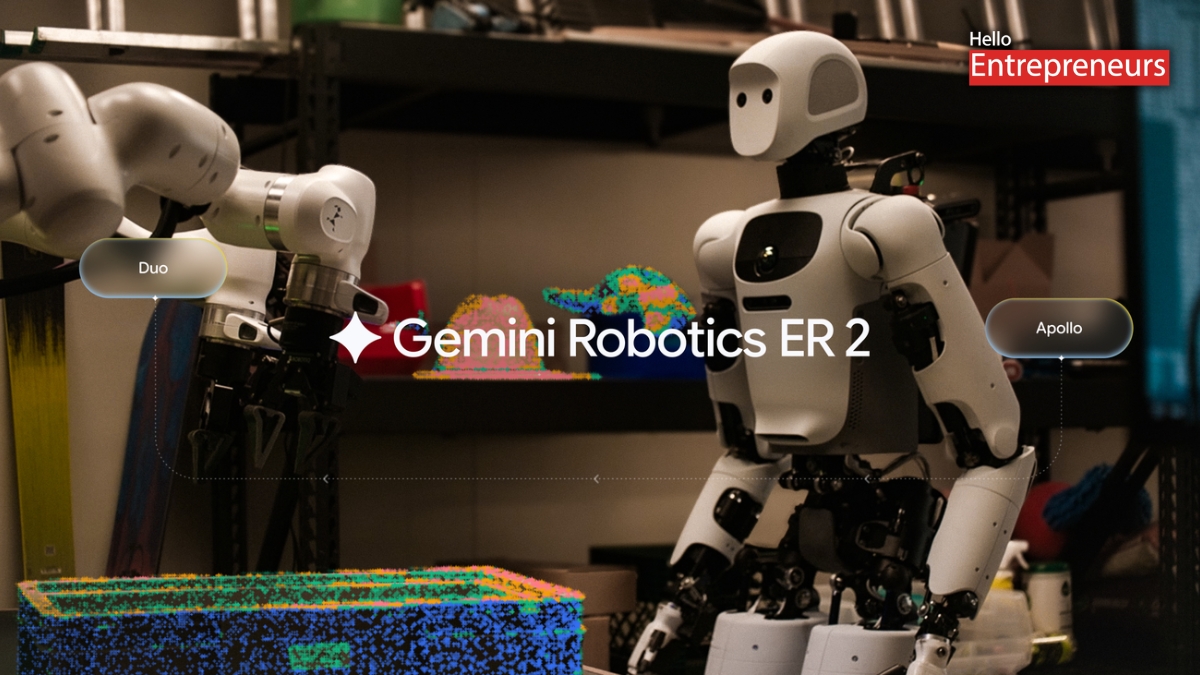
The model offers real-time awareness and enables robots to adjust actions or retry failed steps without restarting the entire workflow. Gemini Robotics ER 2 also unveils multi-robot collaboration by enabling different robots to communicate via shared semantic understanding and coordinate tasks. Different robots can contribute based on their capabilities, such as wheeled robots operating indoors and humanoid robots handling uneven terrain. This capability is demonstrated with Apptronik’s Apollo 2 humanoid robot and Franka F3 Duo, showing how multiple robotic systems can collaborate on shared tasks.
Gemini Robotics ER 2 is going to be available to developers via the Gemini API and Google AI Studio. It will also be available in private preview on the Gemini Enterprise Agent Platform.